Wiki Retrieval Chatbot
Overview
This project was developed as part of CSE 4/535 - Introduction to Information Retrieval at the University at Buffalo. We built an end-to-end retrieval-augmented conversational agent designed to retrieve, rank, and summarize factual information from unstructured Wikipedia articles in response to conversational natural language queries.
Architecture & Pipeline
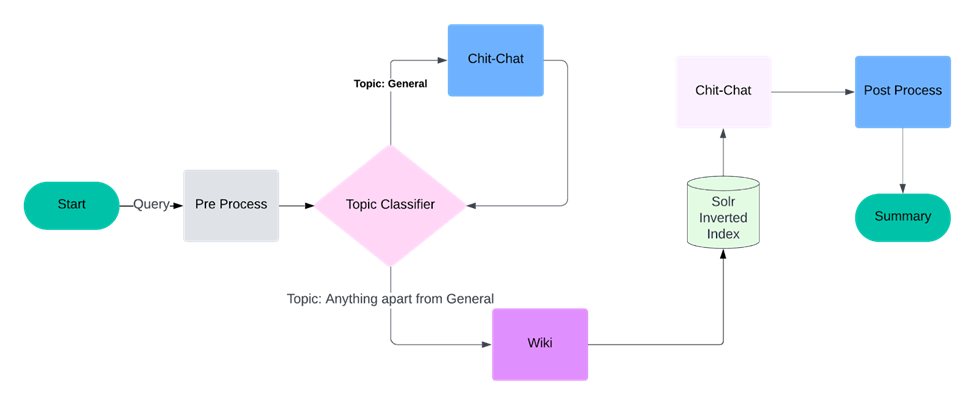 Figure 1: End-to-end Information Retrieval and conversational response pipeline.
- Document Scraping & Normalization: Automated scraping of multi-domain Wikipedia articles with text cleaning, stop-word elimination, and lemmatization.
- Inverted Indexing & Term Weighting: Built an inverted index employing TF-IDF and BM25 relevance scoring algorithms to rank candidate document passages.
- Conversational QA & Dialogue Management: Integrated a conversational scoring layer to preserve context across multi-turn queries, returning accurate factual answers with source citations.