Traffic Light Automation using Reinforcement Learning for Emergency Vehicles
Overview
Emergency response efficiency directly correlates with survival rates in critical incidents. Conventional actuated traffic signals operate on localized static loops, failing to dynamically clear green waves for approaching emergency vehicles.
In this project, we formulate urban traffic signal scheduling as a Markov Decision Process (MDP) and train adaptive agents in a microscopic multi-lane simulation environment (SUMO-RL). We benchmark multiple reinforcement learning algorithms—including SARSA, tabular Q-Learning, Deep Q-Networks (DQN), Double DQN (DDQN), and Advantage Actor-Critic (A2C)—evaluating their capability to minimize emergency vehicle transit latency without triggering congestion collapse across civilian traffic.
- Source Code: GitHub Repository (rishi1134/rl-final)
- Reference Baseline: Diagnosing Reinforcement Learning for Traffic Signal Control (Ault & Benton, 2019)
Environment Setup & MDP Formulation
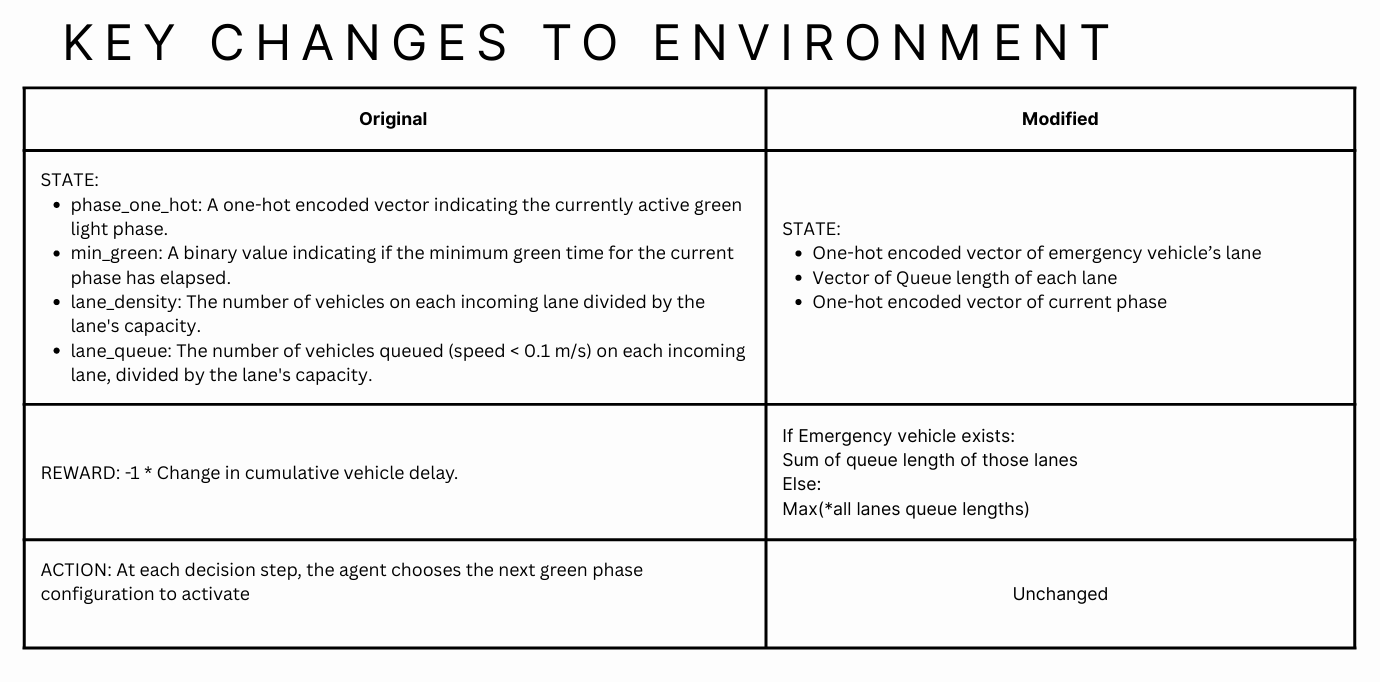 Figure 1: Multi-lane intersection simulation environment in SUMO-RL with emergency vehicle arrivals and phase controllers.
- State Space: Normalized queue lengths per lane, one-hot phase identifiers, and binary indicators for emergency vehicle presence in approach lanes.
- Action Space: Discrete phase selection (hold current green phase vs. advance to next phase with mandatory yellow transition).
- Reward Function: Composite penalty: \(R_t = - \sum_{i} w_i \cdot q_i(t) - \beta \cdot \max_{j \in \text{emergency}} (\tau_j)\) penalizing cumulative queue lengths $q_i$ while applying heavy priority weighting $\beta$ to emergency vehicle wait times $\tau_j$.
Experimental Comparisons & Video Demonstrations
1. Fixed Baseline vs. Learned Policies
The baseline controller operates on a static 42-second green / 2-second yellow cyclic schedule:
2. Deep Q-Network (DQN)
Trained with experience replay buffer (size 500), batch size 32, discount factor $\gamma = 0.99$, and $\epsilon$-greedy exploration:
3. Double DQN (DDQN)
Decouples action selection from value estimation, mitigating Q-value overestimation bias and achieving more stable convergence across peak flow variations:
Critical Empirical Observations
- Reward Shaping & Gaming: Early reward formulations that penalized only sum of queue lengths led to severe policy gaming: the agent learned to keep one lane completely open while allowing the other lane to accumulate massive delays. Balancing maximum wait-time penalties resolved this behavior.
- Phase Granularity: Highly granular phase transitions increased convergence time; enforcing realistic yellow transition constraints yielded far more stable policies.
- Curriculum Episode Sizing: Training initially on shorter episodes followed by evaluation on extended horizon traffic flows yielded the fastest convergence rate.